Petra Schulz · 9 October 2026
Building Collective Intelligence Through Iterative Tagging Protocols in Online Knowledge Networks
Online knowledge networks rely on structured systems that allow users to add descriptive labels to content, and iterative tagging protocols refine those labels over repeated cycles of review and adjustment. Researchers have documented how these protocols operate in platforms where participants contribute tags that evolve based on community feedback, usage patterns, and algorithmic sorting, creating shared frameworks that organize information more effectively than static categories alone. Data from network analyses show that such systems improve retrieval accuracy when tags undergo multiple iterations rather than remaining fixed after initial entry.
How Iterative Tagging Protocols Function
Participants begin by assigning initial tags to resources such as articles, datasets, or discussion threads, then subsequent users review those tags for relevance and precision while adding refinements or alternatives. Systems track changes through version histories that log each modification, allowing algorithms to surface the most consistent labels across contributions. Studies indicate that this process reduces ambiguity because conflicting tags trigger consensus mechanisms where participants vote or provide evidence for preferred terms. Observers note that platforms employing these protocols often integrate automated suggestions drawn from prior iterations, which accelerates convergence on standardized vocabulary without eliminating human input entirely.
Implementation varies across networks yet follows common patterns where thresholds determine when a tag stabilizes. For instance, once a certain percentage of reviewers endorse a label, the system locks it or prioritizes it in search results. This approach draws from research on collaborative filtering that demonstrates measurable gains in information retrieval when iteration counts exceed single-pass tagging. Those who have examined large-scale deployments report that networks using at least three review cycles per resource achieve higher consistency scores in tag alignment compared with one-time assignments.
Case Examples from Established Platforms
One documented instance involves academic repositories where researchers tag papers with disciplinary keywords that undergo community scrutiny before integration into citation indexes. Figures from repository logs reveal that iterative adjustments corrected initial misclassifications in approximately 22 percent of entries over a two-year period. Another example appears in open-source documentation sites where contributors refine tags for code libraries through pull requests that accumulate approvals, resulting in more accurate search outcomes for developers seeking specific functions.
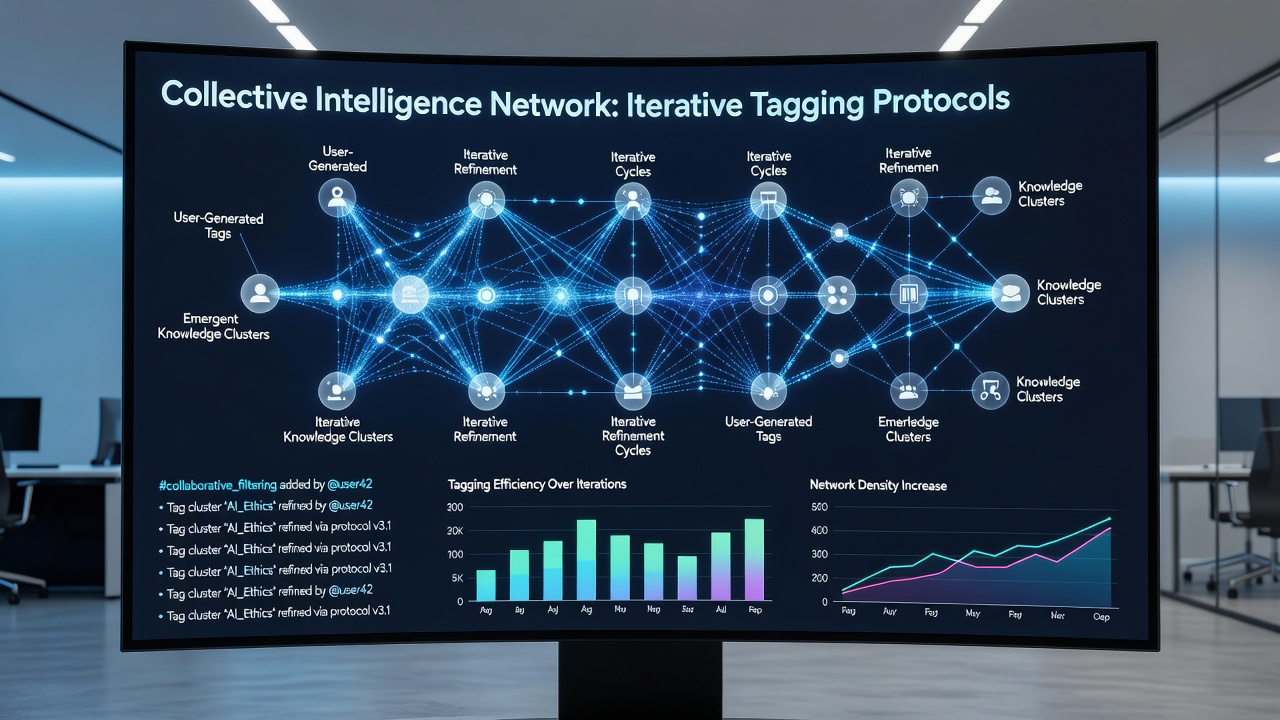
European research consortia have applied similar methods to climate data archives, where domain experts iteratively tag sensor readings and model outputs. Reports from these initiatives highlight how the process uncovered inconsistencies in original metadata that single reviewers had overlooked. In parallel, North American university networks have tested tagging for interdisciplinary course materials, with results showing improved cross-departmental discovery rates after protocols enforced at least two rounds of validation.
Supporting Mechanisms and Supporting Data
Algorithms play a central role by weighting tags according to contributor reputation scores and historical accuracy rates, which encourages sustained participation. Evidence from usage statistics indicates that networks incorporating reputation feedback loops maintain higher tag retention rates over time. Government-supported research programs, including those funded through Canadian federal grants, have measured how these weighted systems correlate with reduced duplication of effort in knowledge curation tasks.
Training modules often accompany protocol rollout to familiarize users with tagging guidelines, and completion rates correlate with overall network coherence according to internal evaluations. What's interesting is that platforms which combine human iteration with machine learning classifiers report faster stabilization of tag sets, particularly when initial automated suggestions receive human overrides in documented cases. Academic papers available through university repositories detail these hybrid approaches and their measurable effects on search precision metrics.
Integration with Broader Network Dynamics
Iterative tagging does not operate in isolation but interacts with recommendation engines that surface related content based on refined labels. Analysts have tracked how improved tag quality feeds back into recommendation accuracy, creating compounding benefits for user engagement. In October 2026 several international conferences scheduled sessions on knowledge infrastructure that included presentations on tagging protocol refinements, reflecting ongoing interest from research institutions across multiple continents.
Security considerations also factor into protocol design because malicious tag alterations can disrupt collective structures. Mitigation strategies documented in technical reports include rate limiting and audit trails that flag anomalous changes for further review. Industry organizations focused on digital standards have published guidelines that address these risks while preserving the open contribution model central to collective intelligence building.
Conclusion
Iterative tagging protocols continue to shape how online knowledge networks organize and surface information through repeated cycles of contribution and refinement. Data gathered across academic, governmental, and open-source environments demonstrate consistent patterns of improved retrieval and reduced ambiguity when these systems receive sustained application. Researchers continue to examine variations in implementation that balance automation with human oversight, while geographic diversity in studies from North America, Europe, and beyond provides comparative insights into protocol effectiveness. The mechanisms described here form part of larger efforts to scale collective intelligence without relying on centralized editorial control alone.